Equivalent experience is the judgment a rubric cannot encode
Rubrics are written for the average candidate. If an application comes from someone who did the same work under a different title, in a different field, or without the required qualification, the rubric has no category for that case.
Those people are often the strongest fit, and they are the first a keyword filter drops. When you decide that experience gained without formal education meets a requirement that is written as a degree, you are judging substance, not labels.
The bias risk must be stated clearly as well. A model that considers equivalence can also weigh prestige, the names of well-known employers, and a writing style associated with a person's background. Restricting the assessment to the written criteria and requiring a quoted passage for each judgment makes the reasoning open to inspection. Those limits do not ensure neutrality.
That is why the output is notes with citations, the number of outputs is limited, and a person reads each application regardless of what the agent has said.
How the agent is built in Agent Studio
Prompt skills state the boundaries. They include each requirement, the kind of evidence that satisfies it, and what does not count: the signals that you have decided are irrelevant, for example, the name of the institution or employer.
Citation is required because the system prompt demands a supporting passage for each judgment, includes "not evidenced" as a possible outcome, and forbids any general score, ranking, or recommendation. Reasons for treating two things as equivalent are allowed. A conclusion about a candidate is not.
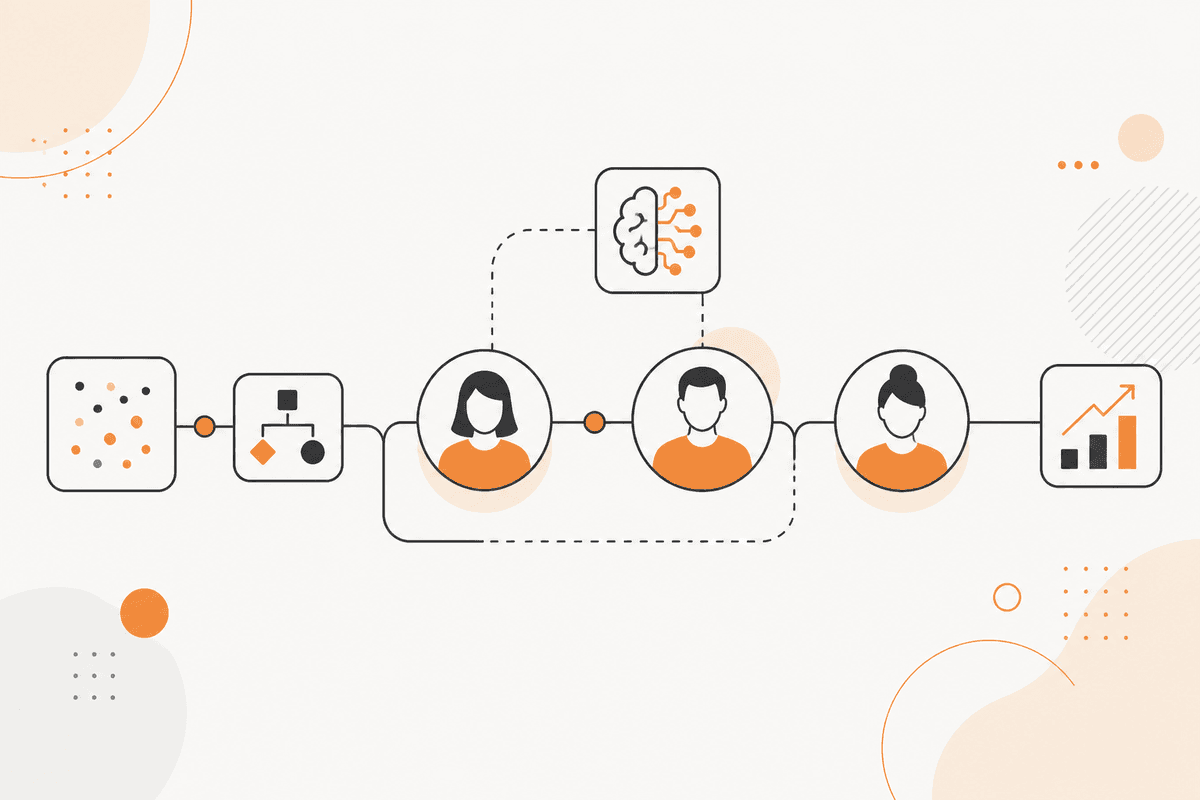
An Airtable node holds the applications and receives the notes. The screening flow then sends each parsed application to the Agent Chat node.
The results are exactly the required set: met, only partially met, or not evidenced, each with the passage, plus a separate section for any equivalence argument. The reviewer should read that equivalence section first.
The agent never rejects an application. Each application goes to a human queue with the notes, in the order that the flow count gives.
The only way to find cases where the agent has consistently missed a type of background is to look for the gap. Make that a monthly routine, not a check you run only in the week after launch. Google Sheets records the agent's assessments next to the reviewer's final decisions.
What this agent is built from
- Prompt skills: the rubric, what satisfies each requirement, and the signals that are explicitly not relevant.
- System prompt: a cited passage per judgment, and no score, ranking, or recommendation permitted.
- Agent Chat (Util): receives each parsed application from the screening flow.
- Airtable (Integration): holds applications and receives the notes beside each one.
- Equivalence field: returned separately, because it is the judgment a reviewer most needs to check.
- Google Sheets (Integration): logs assessments against reviewer decisions for monthly bias review.
- When an ActionFlow is enough: If you only need to check for a required certification, build the workflow. Judging equivalence is the agent's work, and a person still reads everything.
Frequently asked questions
Start building AI workflows
Create a free account, open a template or a blank canvas, and run your first ActionFlow.
Newsletter
Get product updates
New nodes, agents, and product notes. We send mail only when we have something worth opening.